cast.ai
Cast AI LLM Autoscaler
A service for adjusting language-model serving capacity to demand.
https://cast.ai/lp/llm-autoscaler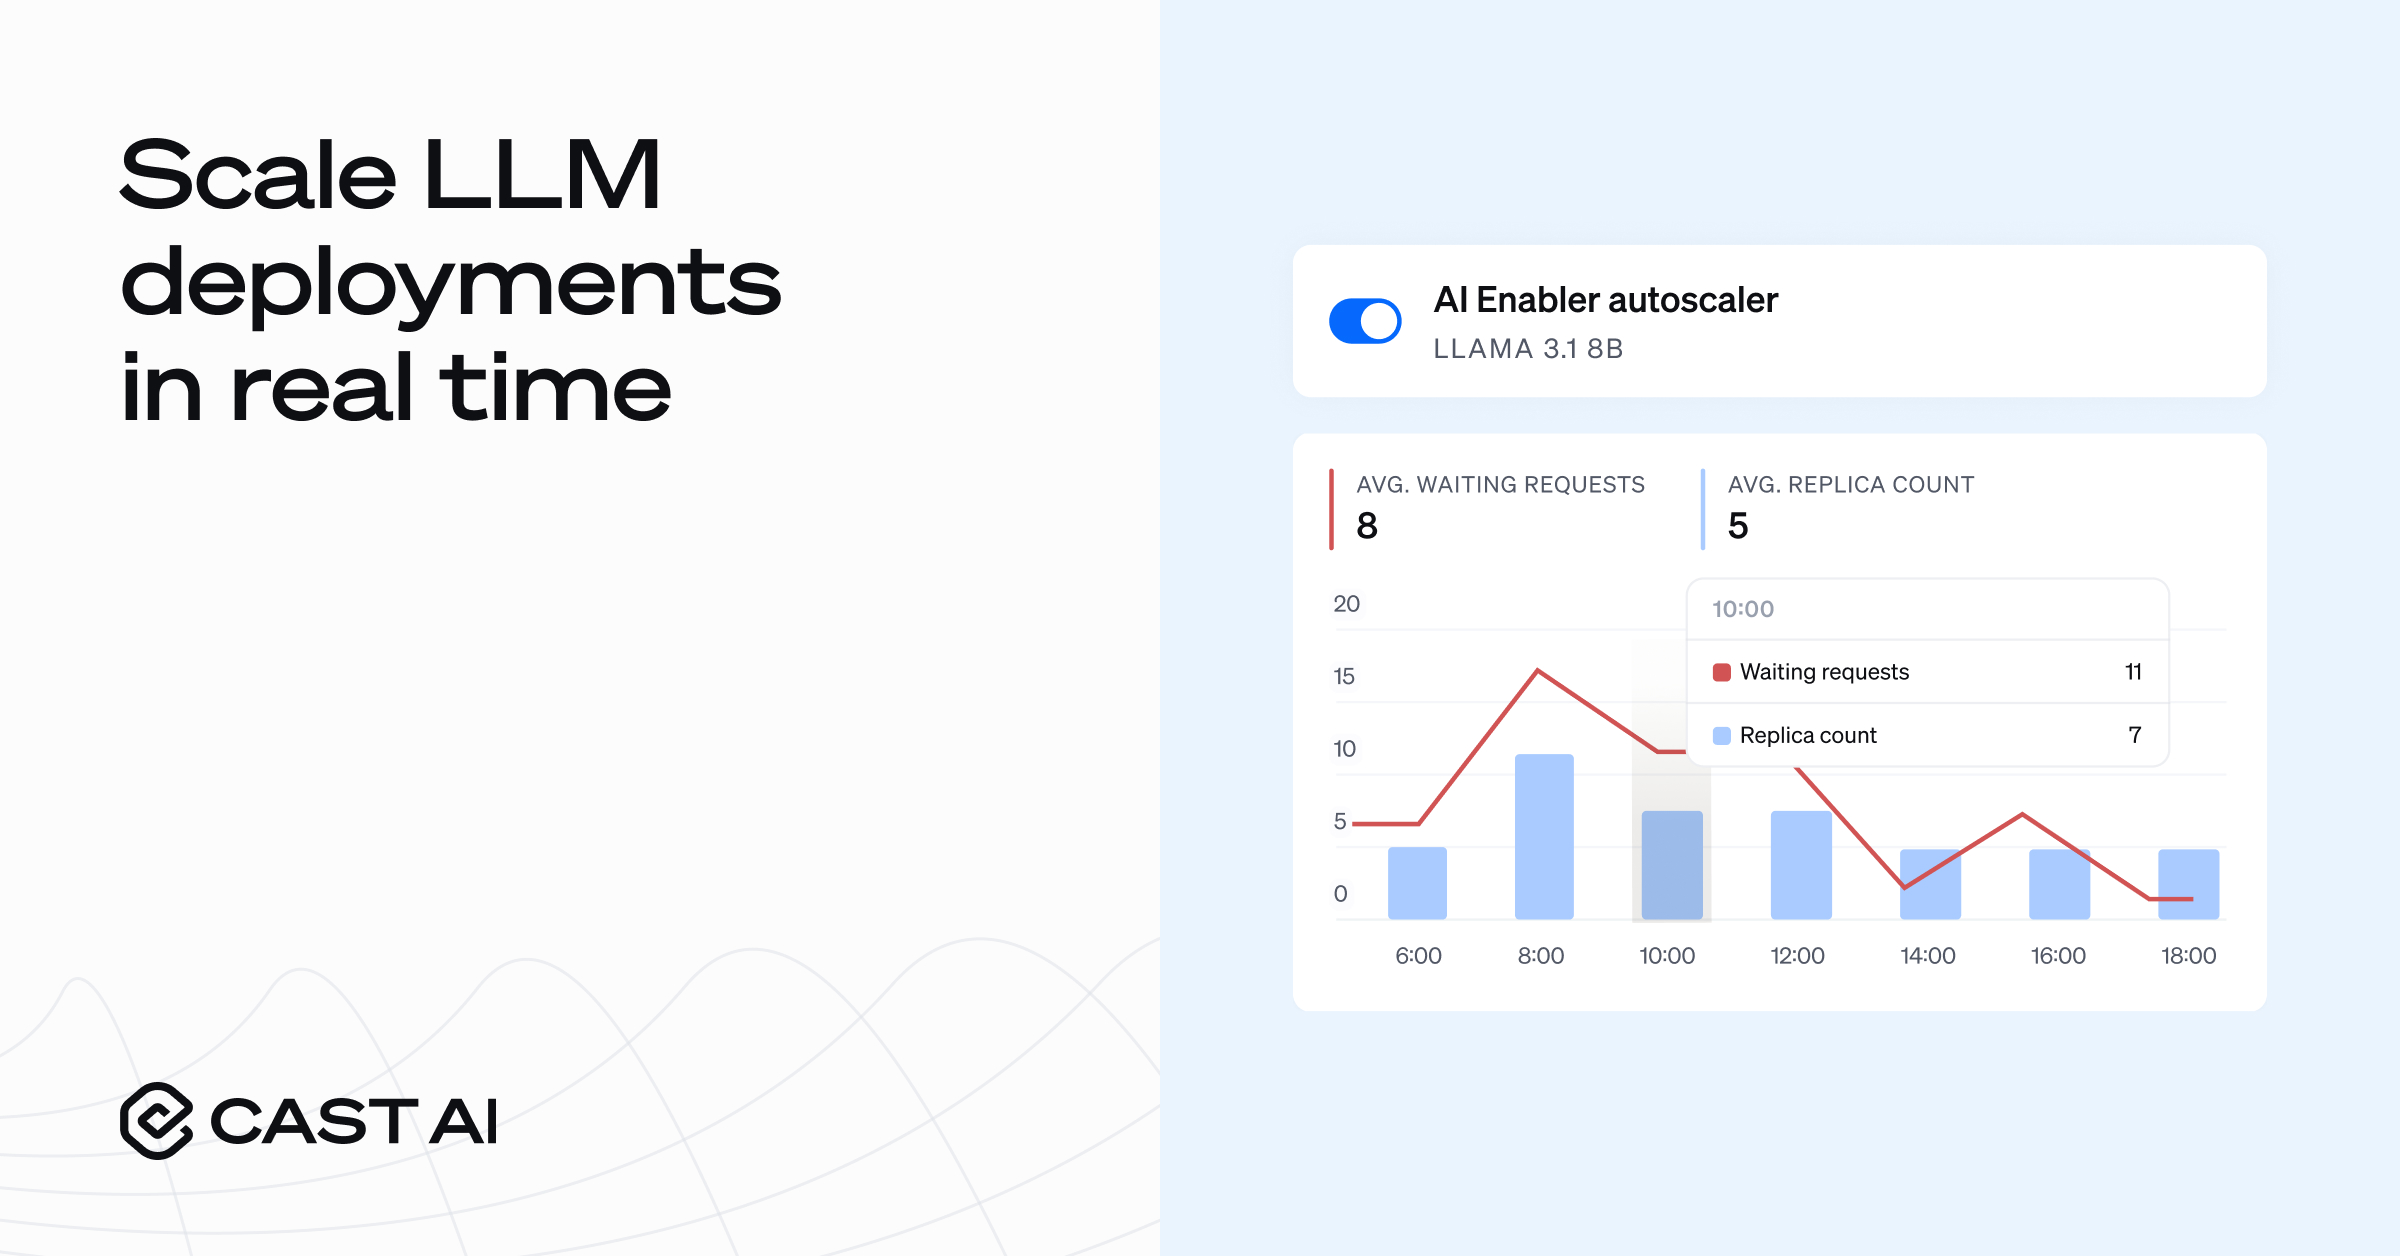
About This Resource
A service for adjusting language-model serving capacity to demand. It focuses on scaling and routing inference workloads to balance available capacity, response times, and infrastructure costs.